PlanFlow: A Trajectory-Aware FPGA Dataflow Architecture for LLM Reinforcement Learning


PlanFlow exposes trajectory semantics as a compact hardware-visible Trajectory Control Token (TCT) and uses it to jointly schedule decode, KV residency, and learner traffic under a shared HBM budget.
- Trajectory Descriptor Engine (TDE) — compresses a short state window into a 64–128 bit TCT
- Unified Utility Scheduler (UUS) — scores every memory request as value-per-byte
- Utility-aware staging — epoch-bounded Stage-Admit / Stage-Sample (not classical unbounded replay)
Soft-prefix conditioning is an optional TCT consumer, not the architectural thesis.
Key Features
- TCT control plane: reuse, urgency, learning utility, and phase fields in one metadata word
- Value-per-byte HBM arbitration: KV, staging, and adapter traffic under one Score(R)=U/C
- Epoch-bounded staging: Δ_max policy-version gating with stored log-probabilities for PPO
- Bandwidth efficiency: η_bw = return / (decode+KV traffic + learner traffic)
Installation
git clone https://github.com/NoakLiu/PlanFlow.git
cd PlanFlow

conda create -n planflow python=3.10 -y
conda activate planflow

pip install -r requirements.txt   # includes pybind11, pytest, torch, …
pip install -e .                  # builds C++ UUS/bandwidth kernels (needs a C++17 compiler)
Quick Start
python examples/train_planflow.py \
    --task webshop \
    --timesteps 200000 \
    --actors 128

python examples/planflow_demo.py
python examples/e2e_hybrid.py --model qwen2.5-14b
Python API
import asyncio
from planflow import PlanFlowTrainer, TrainingConfig

async def main():
    config = TrainingConfig(
        env_name="webshop",
        total_timesteps=100000,
        num_actors=128,
        tct_bitwidth=64,
        enable_soft_prefix=False,  # optional TCT consumer
        device="cuda",
    )
    trainer = PlanFlowTrainer(config)
    metrics = await trainer.train()
    print(metrics.evaluation_results)

asyncio.run(main())
Architecture
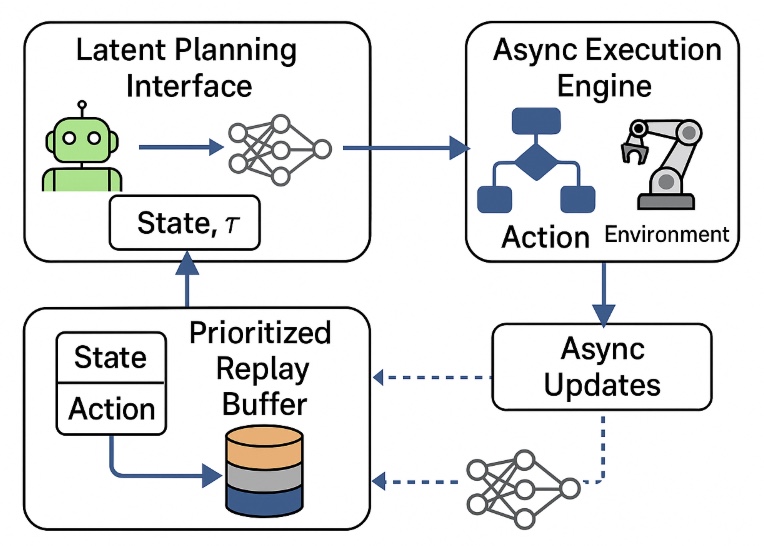
Figure 1: Algorithm architecture — trajectory-aware RL dataflow with TCT conditioning.
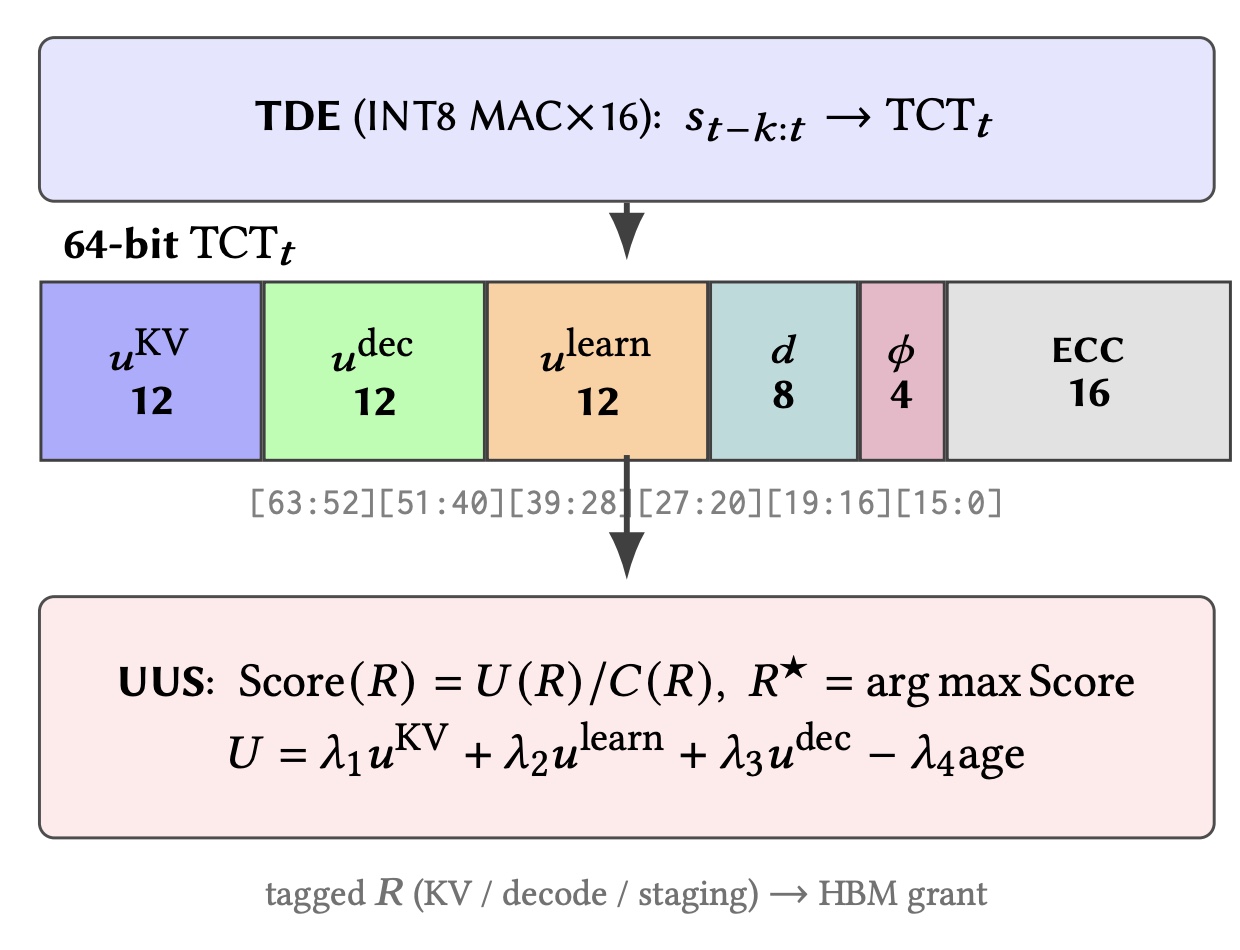
Figure 2: FPGA microarchitecture — HBM/URAM datapath and utility-aware scheduling.
s_{t-k:t} ──► TDE ──► TCT_t (64b)
                        │
        ┌───────────────┼───────────────────┐
        ▼               ▼                   ▼
  soft-prefix*     UUS Score(R)=U/C    staging U_adm
  (optional)       HBM/URAM grants     Stage-Admit/Sample
Bandwidth view
B(π) = E[Σ_t b(s_{1:t})] + E_S[w |ℓ_PG|]
η_bw(π) = E[Σ r_t] / B(π)
PlanFlow raises η_bw by refusing low-utility bytes when HBM ports are saturated.
TCT packing (default 64-bit)
| Field | Bits | Role |
|---|---|---|
| u_KV | 12 | predicted KV reuse utility |
| u_dec | 12 | decode urgency |
| u_learn | 12 | learning utility |
| d_reuse | 8 | reuse-distance bucket |
| φ_phase | 4 | rollout phase |
| ECC | 16 | spare / parity |
UUS scoring
U(R) = λ1·u_KV + λ2·u_learn + λ3·u_dec·I_decode − λ4·age(R)
C(R) = bytes + γ·lat_c(R)
Score(R) = U(R) / C(R)
Core API
from planflow.core import (
    TrajectoryDescriptorEngine, TDEConfig,
    UnifiedUtilityScheduler, UUSConfig, MemoryRequest, RequestType,
    TrajectoryStagingBuffer, StagingConfig,
    pack_tct, unpack_tct,
)

# TDE → TCT
tde = TrajectoryDescriptorEngine(TDEConfig(state_dim=512, window_k=4))
tct = tde.emit_tct(state_window)  # torch [k+1, D]

# UUS grant
uus = UnifiedUtilityScheduler(UUSConfig())
req = MemoryRequest(
    stream_id=0, req_type=RequestType.DECODE, addr=0, bytes=256,
    tct=tct, age=0.1, lat_c=0.1,
)
print(uus.score(req))
grants = uus.grant([req])

# Epoch-bounded staging
staging = TrajectoryStagingBuffer(StagingConfig(delta_max=4))
staging.stage_admit(state, action, reward=1.0, log_prob_old=-0.5, tct=tct)
batch, weights = staging.stage_sample(batch_size=32)
Systems Results (Alveo U280)
Compared with GPU PPO under full FPGA+GPU+host power accounting, PlanFlow reduces external-memory traffic by up to 43% (0.57× on Mistral-7B) and improves full-system tokens-per-joule by up to 2.15× (Llama-3.1-8B), with Success@1 within 0.6 percentage points of software EchoRL.
Sys W = average (P_{\mathrm{FPGA}}+P_{\mathrm{GPU}}+P_{\mathrm{host}}). †Base GEMMs on a coupled GPU; TDE/UUS/KV remain FPGA-resident.
| Model | Method | ETPS | Hit% | Traffic | Sys W | Sys tok/s/W |
|---|---|---|---|---|---|---|
| Qwen2.5-7B | GPU PPO | 1540 | 54.1 | 1.00× | 98.4 | 1.00× |
| Qwen2.5-7B | Cache-only | 1690 | 59.2 | 0.72× | 64.8 | 1.67× |
| Qwen2.5-7B | TD-PRB port | 1688 | — | 0.70× | 61.8 | 1.75× |
| Qwen2.5-7B | PlanFlow | 1768 | 63.8 | 0.59× | 52.7 | 2.14× |
| Llama-3.1-8B | GPU PPO | 1485 | 52.8 | 1.00× | 105.0 | 1.00× |
| Llama-3.1-8B | Cache-only | 1628 | 57.4 | 0.74× | 69.2 | 1.66× |
| Llama-3.1-8B | TD-PRB port | 1624 | — | 0.72× | 65.9 | 1.74× |
| Llama-3.1-8B | PlanFlow | 1702 | 61.5 | 0.61× | 56.1 | 2.15× |
| Gemma-2-9B | GPU PPO | 1416 | 53.0 | 1.00× | 107.8 | 1.00× |
| Gemma-2-9B | Cache-only | 1564 | 57.0 | 0.75× | 72.4 | 1.64× |
| Gemma-2-9B | TD-PRB port | 1560 | — | 0.73× | 69.2 | 1.72× |
| Gemma-2-9B | PlanFlow | 1640 | 60.6 | 0.62× | 59.5 | 2.10× |
| Mistral-7B | GPU PPO | 1524 | 53.7 | 1.00× | 99.1 | 1.00× |
| Mistral-7B | Cache-only | 1672 | 58.7 | 0.71× | 65.4 | 1.66× |
| Mistral-7B | TD-PRB port | 1668 | — | 0.69× | 62.8 | 1.73× |
| Mistral-7B | PlanFlow | 1748 | 63.4 | 0.57× | 53.6 | 2.12× |
| Qwen2.5-14B† | GPU PPO | 1112 | 51.3 | 1.00× | 142.0 | 1.00× |
| Qwen2.5-14B† | Cache-only | 1176 | 55.3 | 0.78× | 127.0 | 1.18× |
| Qwen2.5-14B† | TD-PRB port | 1174 | — | 0.76× | 124.5 | 1.20× |
| Qwen2.5-14B† | PlanFlow | 1210 | 58.9 | 0.67× | 118.0 | 1.31× |
| Qwen2.5-24B† | GPU PPO | 836 | 50.6 | 1.00× | 172.0 | 1.00× |
| Qwen2.5-24B† | Cache-only | 928 | 53.5 | 0.76× | 147.5 | 1.29× |
| Qwen2.5-24B† | TD-PRB port | 948 | — | 0.73× | 141.2 | 1.38× |
| Qwen2.5-24B† | PlanFlow | 1048 | 56.4 | 0.63× | 128.1 | 1.68× |
Success@1 at 200K steps (mean±std):
| Task | Model | PPO | GRPO | Soft. EchoRL | PlanFlow |
|---|---|---|---|---|---|
| WebShop | Qwen2.5-7B | 63.5±1.1 | 64.8±1.0 | 67.2±0.9 | 66.8±1.0 |
| WebShop | Qwen2.5-24B | 72.4±1.0 | 73.8±0.9 | 76.3±0.8 | 75.8±0.9 |
| Game24 | Qwen2.5-14B | 79.2±0.9 | 80.1±0.9 | 82.6±0.8 | 82.1±0.9 |
| CRUXEval | Qwen2.5-7B | 64.5±1.0 | 65.3±0.9 | 67.8±0.8 | 67.4±0.9 |
| ALFWorld | Llama-3.1-8B | 71.2±1.2 | 72.6±1.1 | 75.4±1.0 | 74.9±1.1 |
| GSM8K | Gemma-2-9B | 68.4±0.8 | 70.1±0.9 | 73.6±0.7 | 73.1±0.8 |
| HumanEval | Mistral-7B | 52.8±1.3 | 54.1±1.2 | 57.9±1.0 | 57.4±1.1 |
See exp.md for HBM throttle, FPGA-RL ports, TCT bitwidth, and ablations.
Supported Tasks
WebShop, Game24, CRUXEval, ALFWorld, GSM8K, HumanEval (paper evaluation); ARC and MiniGrid remain available as environment interfaces.
FPGA RTL (Alveo U280)
SystemVerilog under rtl/: TCT pack, TDE, UUS, KV cuckoo, staging,
CSR, 6× HBM AXI shims, 300/250 MHz CDC, and Vitis kernel planflow_kernel.
Build recipe: rtl/README.md (synth_u280.tcl + package_xclbin.sh).
Without Vivado the Python runtime uses a bit-accurate co-sim of the same control plane.
cd rtl/tb && make all    # iverilog smoke: TCT pack, Eq.19, CDC FIFO
python examples/e2e_hybrid.py --model qwen2.5-24b --device cpu
14B/24B base GEMMs run on a coupled GPU (UUS-gated); standalone 7B–9B keep
quantized adapter + decode WS in the 8 GB HBM (Gemma-2-9B uses INT4).
S_desc ≤ 280 B; T_eff = max(T_rollout, T_DMA+T_PPO).
Python package: planflow (formerly echo_rl).
Testing
pytest tests/
python examples/planflow_demo.py
License
MIT